Defending Agentic LLM Systems against Prompt Injection and Tool Abuse
Defending Agentic LLM Systems against Prompt Injection and Tool Abuse
Description
Details
Context and Problem Statement
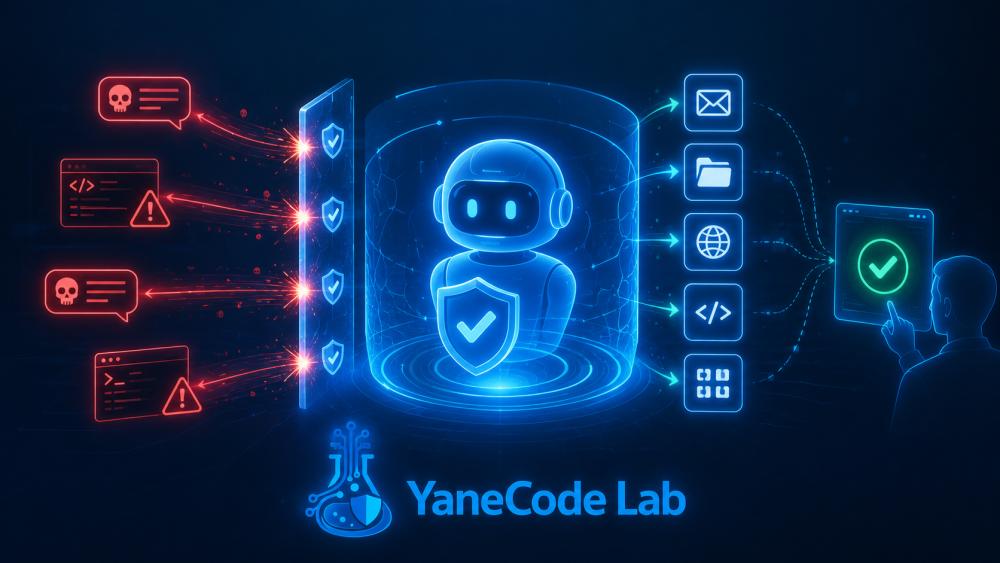
LLM-based agents consume untrusted content such as web pages, emails, and documents while accessing tools capable of acting on external systems. Instructions embedded in data can therefore redirect the agent toward unintended actions, while text-level filtering remains fragile against indirect attacks.
Research Question
Does programmable privilege control at the tool layer reduce the attack surface more effectively than prompt filtering at the text layer, and what functional cost does such protection impose?
Proposed Approach
Design a mediation layer between the agent and its tools that enforces least privilege by task, human confirmation for irreversible actions, and isolation of untrusted data. A structured attack benchmark measures compromise rate, false blocking, and utility degradation.
Expected Contribution
A comparative evaluation of defense families using a joint security-utility metric on a reproducible benchmark.
Expected Prototype
A reusable tool-mediation library with automated red-team scenarios and a coverage report.
Datasets
Published prompt-injection scenarios and an agent-task corpus built for isolated experimentation.
Challenges
Defining data-instruction boundaries, combinatorial attack diversity, unstable benchmarks, and the trade-off between security and usability.
Research Question
Innovation
Expected Deliverable
Technologies
Required Skills
- Application Security and Threat Modeling
- Python Software Development and Agent Architecture
- Access-Control and Policy-Verification Fundamentals
- Experimental Methodology
Datasets
- Prompt-injection scenarios from academic publications
- Agent task corpus developed for controlled experimentation