Synthetic Data Generation and Privacy Auditing for Cross-Border Medical Model Sharing
Synthetic Data Generation and Privacy Auditing for Cross-Border Medical Model Sharing
Description
Details
Context and Problem Statement
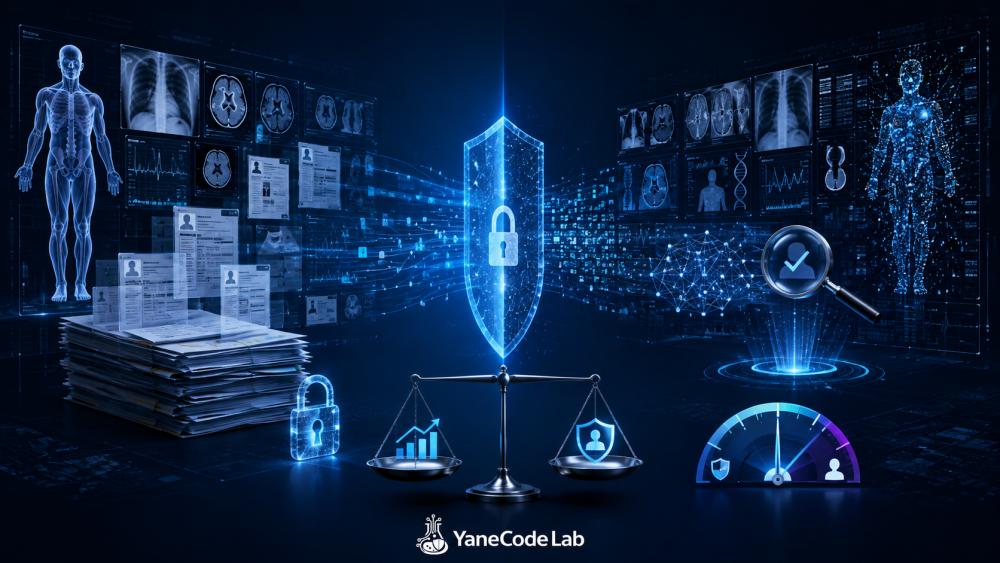
Synthetic-data generation is increasingly proposed as an alternative to direct medical-data sharing or federated learning. However, privacy and utility are often evaluated separately using weak proxies, and synthetic records may still leak information about source patients.
Research Question
What level of clinical utility remains achievable when a generative model is constrained by a privacy budget that is subsequently audited using empirical membership-inference attacks?
Proposed Approach
Train generative models with and without differential privacy, including diffusion models for images and tabular generators for structured records. Audit privacy using membership-inference and reconstruction attacks, and evaluate utility by training downstream clinical models on synthetic data and testing them on real held-out data.
Expected Contribution
An empirical privacy-utility curve across at least two medical modalities, establishing when synthetic sharing can credibly substitute for real-data exchange.
Expected Prototype
An automated generation-and-audit pipeline producing a technical datasheet with measured downstream utility and estimated re-identification risk.
Datasets
CheXpert, MIMIC-IV, and synthetic datasets generated during the project.
Challenges
Underpowered privacy attacks, computational cost, bias amplification, and uncertain regulatory status of synthetic medical data.
Research Question
Innovation
Expected Deliverable
Technologies
Required Skills
- Deep Generative Models
- Differential Privacy and Model Attacks
- Medical Data Processing
- GPU Computing
Datasets
- CheXpert
- MIMIC-IV (PhysioNet, controlled access)
- Synthetic datasets produced during the project